On this page4
Google Search Console is one of the most used tools in the search marketing world.
It is particularly useful when examining the status of pages in terms of Google’s three main systems:
Crawling, Indexing, and Ranking
We’ve compiled a list of some of the most frequent Google Search Console errors, as well as instructions for determining what’s generating the mistake and, in most cases, how to repair it.
Where & When do Google Search Console Errors Occur?
The bulk of GSC issues occur during Google’s three key interactions with your website: crawling, indexing, and serving.
Disruptions or stops in any phase of Google’s three-step procedure can lead to many common issues with Google Search Console. Here are some typical mistakes:
You can see how each stage in the process affects your site by breaking it down into its parts.
Step 1: Crawling
“Crawling begins with Google discovering new URLs via an updated sitemap, following a new internal or external link, etc.”
This is when Google first comes into touch with your website, including its content, metadata, pages, and other features.
This procedure is nearly immediate, and it may be many weeks before Google scans your site again.
A lot might happen during this period that causes Google to generate a GSC error; your site could have broken links, private non-indexable pages, a faulty sitemap, a complicated SEO schema, and so on.
Step 2: Indexing
This is perhaps the most thorough action Google takes against your website. When they initially crawl your site, they are determining whether it is active, genuine, and a functional “website,” so to speak.
However, during the Indexing phase, Google thoroughly examines your content, SEO data, keywords, and entire site to determine which google search engine results pages your material may appear on.
Similar to the crawling phase, the indexing step might encourage Google to assume your site contains more flaws and issues.
This is also when Google analyzes whether there is any duplicate material, plagiarism, or other violations/errors that contradict their stated policy.
Step 3: Serving
Once Google has crawled your site and indexed your information, they will begin to “serve” it to individuals searching Google for answers.
Google does not promise complete completion of any of these phases for your site, since they are a company focused on providing the greatest experience for its users rather than a free public service.
Why Are Google Search Console Errors Important?
Google Search Console mistakes are essential for several reasons:
1. Identification: These errors give information about potential issues that may be affecting your website’s performance on Google’s search engine results pages.
2. Optimization: Correcting these issues can boost your website’s exposure, ranking, and organic search traffic.
3. User Experience: Correcting mistakes such as crawl faults and mobile usability concerns offers a smooth browsing experience for your target audience.
4. Site Health: Google Search Console problems help you identify and resolve technical issues such as indexing errors and ensure that your website functions correctly.
5. Insights: Understanding these problems offers useful information about how Google views your website and may help direct your SEO activities for improved performance.
By identifying and addressing issues in Google Search Console, website owners can improve their online presence and provide a better user experience for their audience.
Types of Google Search Console Errors & Ways to Resolve Them
a. Server error (5xx)
If Google returns a server error, it signifies that something is preventing its crawler, Googlebot, from accessing and ranking the website. There are three main types of server problems.
500: 500 is an ‘internal server error’ that indicates that technical difficulties are forcing the server to delay executing the request.
This might be due to numerous factors. There might be a coding issue with your CMS, incorrect PHP code on your website, or another cause completely.
502 errors are ‘bad gateway’ errors. An upstream service did not respond, causing a delay in processing your request.
The upstream might execute on the same machine or a whole separate machine. In most cases, a 502 error indicates a problem with your content management system (CMS), such as WordPress.
503 errors are ‘ service unavailable’ messages. The server is overloaded, undergoing maintenance, or completely down, causing Googlebot to take longer to visit the site. Googlebot only waits a set period before giving up and returning a 5xx error.
To resolve this issue so that Googlebot may crawl your website, first determine whether the server error is a 500, 502, or 503 error. This is something your IT department/staff can assist with.
b. 404 Errors
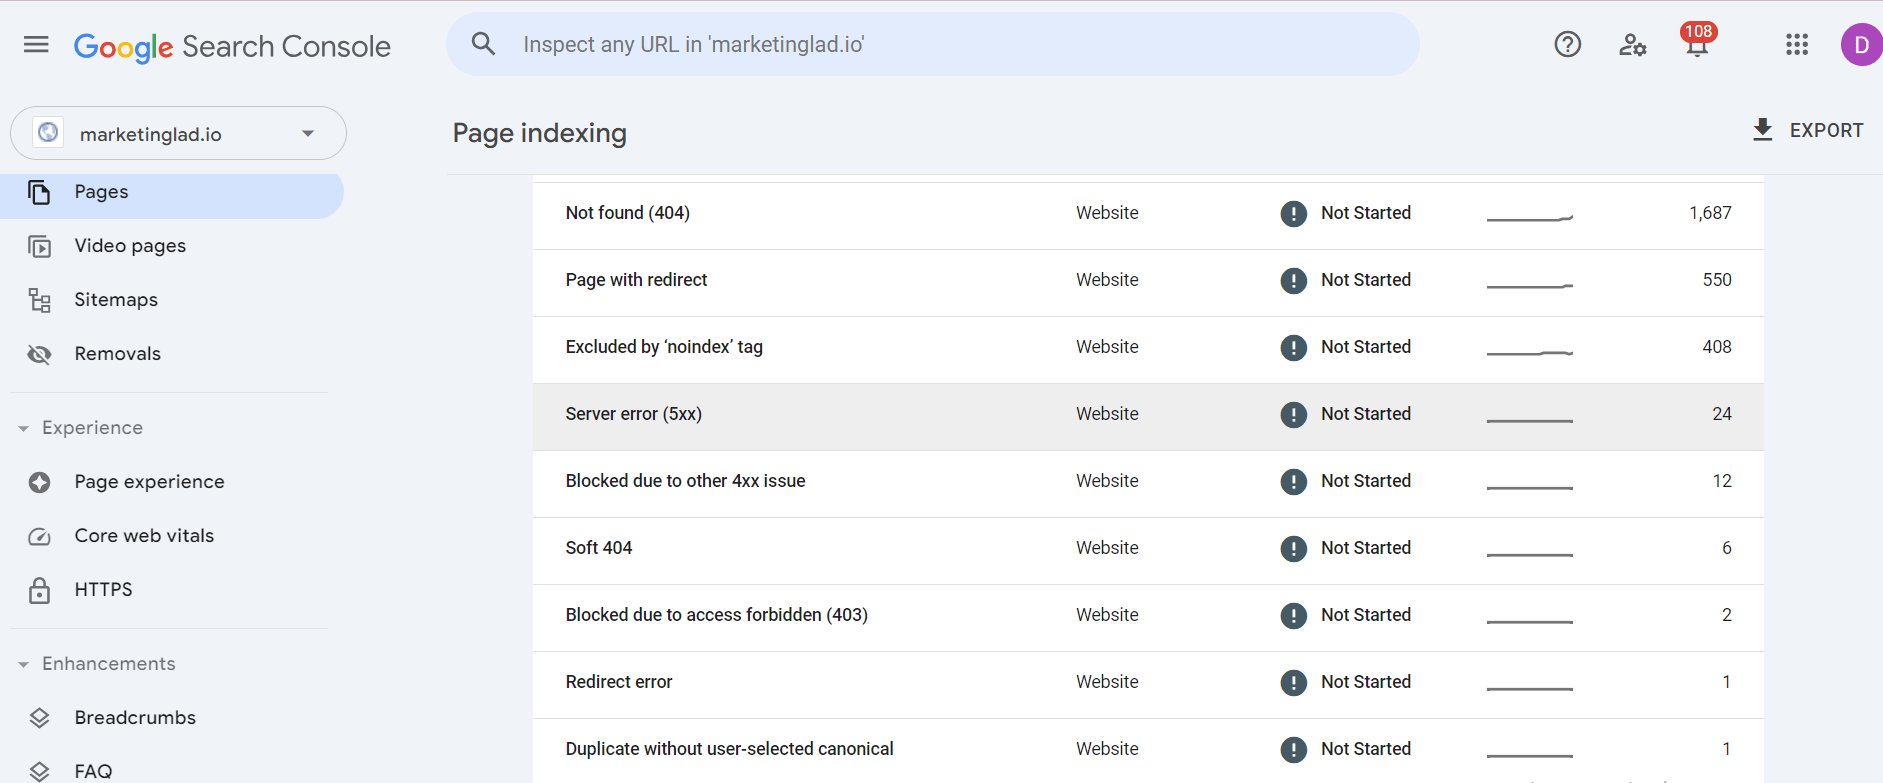
A “404 error” indicates that Googlebot cannot find a page. Typically, it is no longer accessible to the bot, or the page has become blank. 404 errors are not uncommon as websites evolve and change, and they are not necessarily an issue.
Here are a few distinctions between when this issue will occur and what you should do (if anything) to correct it:
1. The submitted URL appears to be a soft 404

- Somebody submitted this page for indexing at some point, but the server now delivers a blank or virtually empty page.
- If the page is no longer available and there is no apparent replacement, set your server to deliver a 404 (not found) or 410 (gone) response code.
- If the page has relocated or has a clear replacement, configure the necessary 301 redirect (permanent redirect).
2. The submitted URL was not found (404 error)

- A URL from your sitemap no longer exists. We may need to delete a page (resulting in a 404), which is acceptable.
- For example, you might remove a defunct product with no equivalent replacement or erase old blog entries that have gotten no traffic, no links, and do not rank for any keywords.
- A few 404s will need to be repaired.
- If a URL should exist but has moved, add a 301 redirect; you may even do this if a discontinued product has a suitable replacement (such as a newer model).
- If the URL is unknown or you intend to permanently erase the material, disregard the 404 error.
- Eventually, Googlebot will stop searching for these pages.
c. Blocked by Robots.txt file
If you see this message, it implies Google was unable to obtain your robots.txt file.
What is that?
A robots.txt file allows you to specify page content that you do not want search engines to index. As previously mentioned, there are several reasons you might not want certain pages to appear in search engines.
These are generally administrative pages that provide no value to readers and are not part of your SEO strategy.
You are required to have a robots.txt file only if you want to prevent your web pages from being indexed. You don’t need one if Google can crawl and index every page on your site without issue.
All Googlebot will do is index your whole website. That’s not a significant concern for tiny sites, but larger sites frequently use the noindex tag to hide content.
This error occurs when Google is unable to load a robots.txt file. You must address this urgent matter, or your website will not be scanned or indexed.
- Using a robots.txt tester is a reliable technique to resolve this issue.
- It will notify you whether there is a problem with the file.
- Beyond using this tool, you should perform a thorough review to ensure the file is set correctly.
- Check the file to ensure that it is not crawling any pages you do not want it to.
- Aside from that, you should search for one piece of code in particular: ‘Disallow:/’.
- If you see it, eradicate it right away.
- It should not be in your robots.txt file since it will prevent your website from appearing on Google.
- If your robots.txt file is still causing problems and you’re unsure why, it is recommended that you delete it.
That’s because it’s preferable to go without a robots.txt file than to have one that’s incorrectly configured. If you do not have one, Google will scan your website as usual. If you have one that isn’t properly configured, the crawling will not occur until you fix the problem.
d. URL designated as ‘noindex’
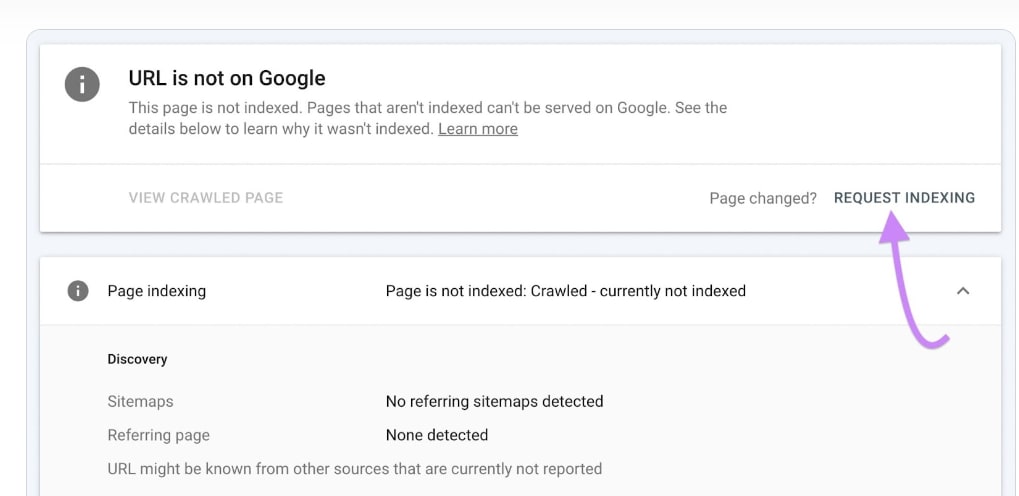
If you notice a URL marked ‘noindex’ error, it signifies that Google has discovered a page you want indexed (most likely because it appears in your website’s sitemap or as an internal link), but something is preventing Google from indexing it.
There are two possible explanations for this. Either a noindex meta tag in the page’s HTML or an X-Robots-Tag HTTP header. Googlebot will see this and be unable to index your page.
If you get this error, check your page’s source code to see if you can find the noindex meta tag or the X-Robots-Tag that displays noindex, and delete it. Resubmit the URL using Google Search Console, and you should be good to go.
e. False Mobile Usability Scores
This issue indicates that some pages on your site are not optimized for mobile devices, with issues such as slow loading or poor content formatting.
GSC may notify you that your site is failing several scores, such as this one. Don’t worry; this issue might lead to inaccurate AI results for your website.
Major websites, such as CNN and ESPN, often have stories that are not optimized for mobile devices. Nonetheless, they continue to score strongly for a wide range of prominent keywords.
Outstanding content is usually more significant than Google metrics, which are run by AI programs. The fact is, that exceptional content carries more weight than these metrics.
These programs may just be incorrect; instead, focus on providing high-quality content and making your site as mobile-friendly as possible.
Examine your website on your own mobile devices to get a sense of the experience.
Give this a quick read: How To Do Deindexing? Effective Methods Are Explained Here!
Conclusion
This is a summary of the most common Google Search Console Errors. Remember that to rank on search engines, you will need a Googlebot to effectively discover, crawl, and index your website.
Many mistakes can arise throughout each of these phases, which is why GSC is such an effective tool. Remember to check the response codes for each URL to ensure they add up.
Additionally, you should verify live URLs to ensure there are no redirect problems.
As long as you pay close attention to the Index Coverage Tab and your legitimate URLs, you should be able to keep your domains working well. That way, Google will have no issue scanning and indexing them, and your SEO efforts will have a chance to pay off.
Do you want your domains to perform without errors so you can earn the greatest traffic and revenue?
If this is the case, please book a conversation with one of our trained experts right away.
Our staff can help you revolutionize your SEO strategy.
Frequently Asked Questions
Indexing is the process by which search engines view and analyze new and updated web pages before adding them to their index (database) of websites. Three ways to accomplish indexing are: Let the crawlers do their thing. Submit a sitemap (XML format). Manual indexing of requests.
In Google Search Console, go to “Coverage” and look for any issues or warnings. Address these issues to guarantee appropriate crawling and indexing. Low-quality material: If pages contain thin or duplicate content, they may not be indexed by search engines. Ensure that your pages include original and valuable information.
A sitemap is a file on your website that tells Google which pages it should know about. If you’re using a web hosting provider like Squarespace or Wix, they’ll generally handle your sitemap for you, so you don’t need to create one or utilize this report.